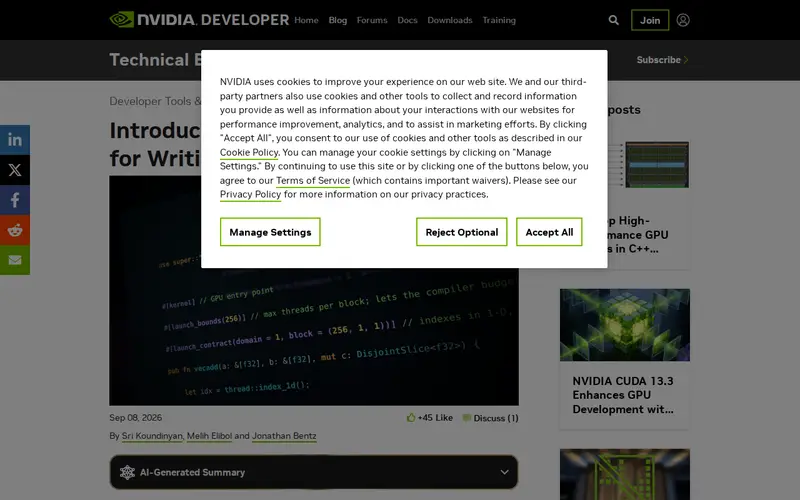
Nvidia has announced native GPU programming capabilities for Rust developers with the introduction of CUDA-Rust. This initiative aims to bring the safety and performance benefits of Rust to the massively parallel world of GPU computing. Developers can now write GPU kernels using Rust, enabling them to leverage Nvidia's hardware for computationally intensive tasks with greater confidence and potentially reduced development time. This opens up new possibilities for high-performance computing, machine learning, and scientific simulations.
Editorial check
How this page is checked
Source trail
developer.nvidia.com
External links are separated from Surfaced commentary.
Reader safety
Context before clicks
Product links and external services are not presented as guarantees.
Monetization
No affiliate flag
Ads and commerce links are kept distinct from editorial text.
Surfaced take
Why It’s Useful
This is a significant development for GPU programming, as Rust's memory safety features can help prevent common bugs and vulnerabilities that plague C/C++ code often used in GPU development. For developers already familiar with Rust's ecosystem, it provides a compelling path to harness GPU power without the steep learning curve or safety concerns associated with traditional CUDA C/C++. It's particularly valuable for researchers and engineers who need to build performant, reliable parallel applications and want to avoid memory-related errors that are notoriously difficult to debug on GPUs. The dual-track approach signals a commitment to broad adoption.
In everyday life
When you’d actually reach for this
Imagine you're a researcher working on a complex simulation. With CUDA-Rust, you can write your GPU kernel in a safer language, reducing the chances of crashes or incorrect results due to memory errors. This allows you to focus more on the scientific problem at hand rather than debugging low-level memory issues.



Enjoyed this? Get five picks like this every morning.
Free daily newsletter — zero spam, unsubscribe anytime.